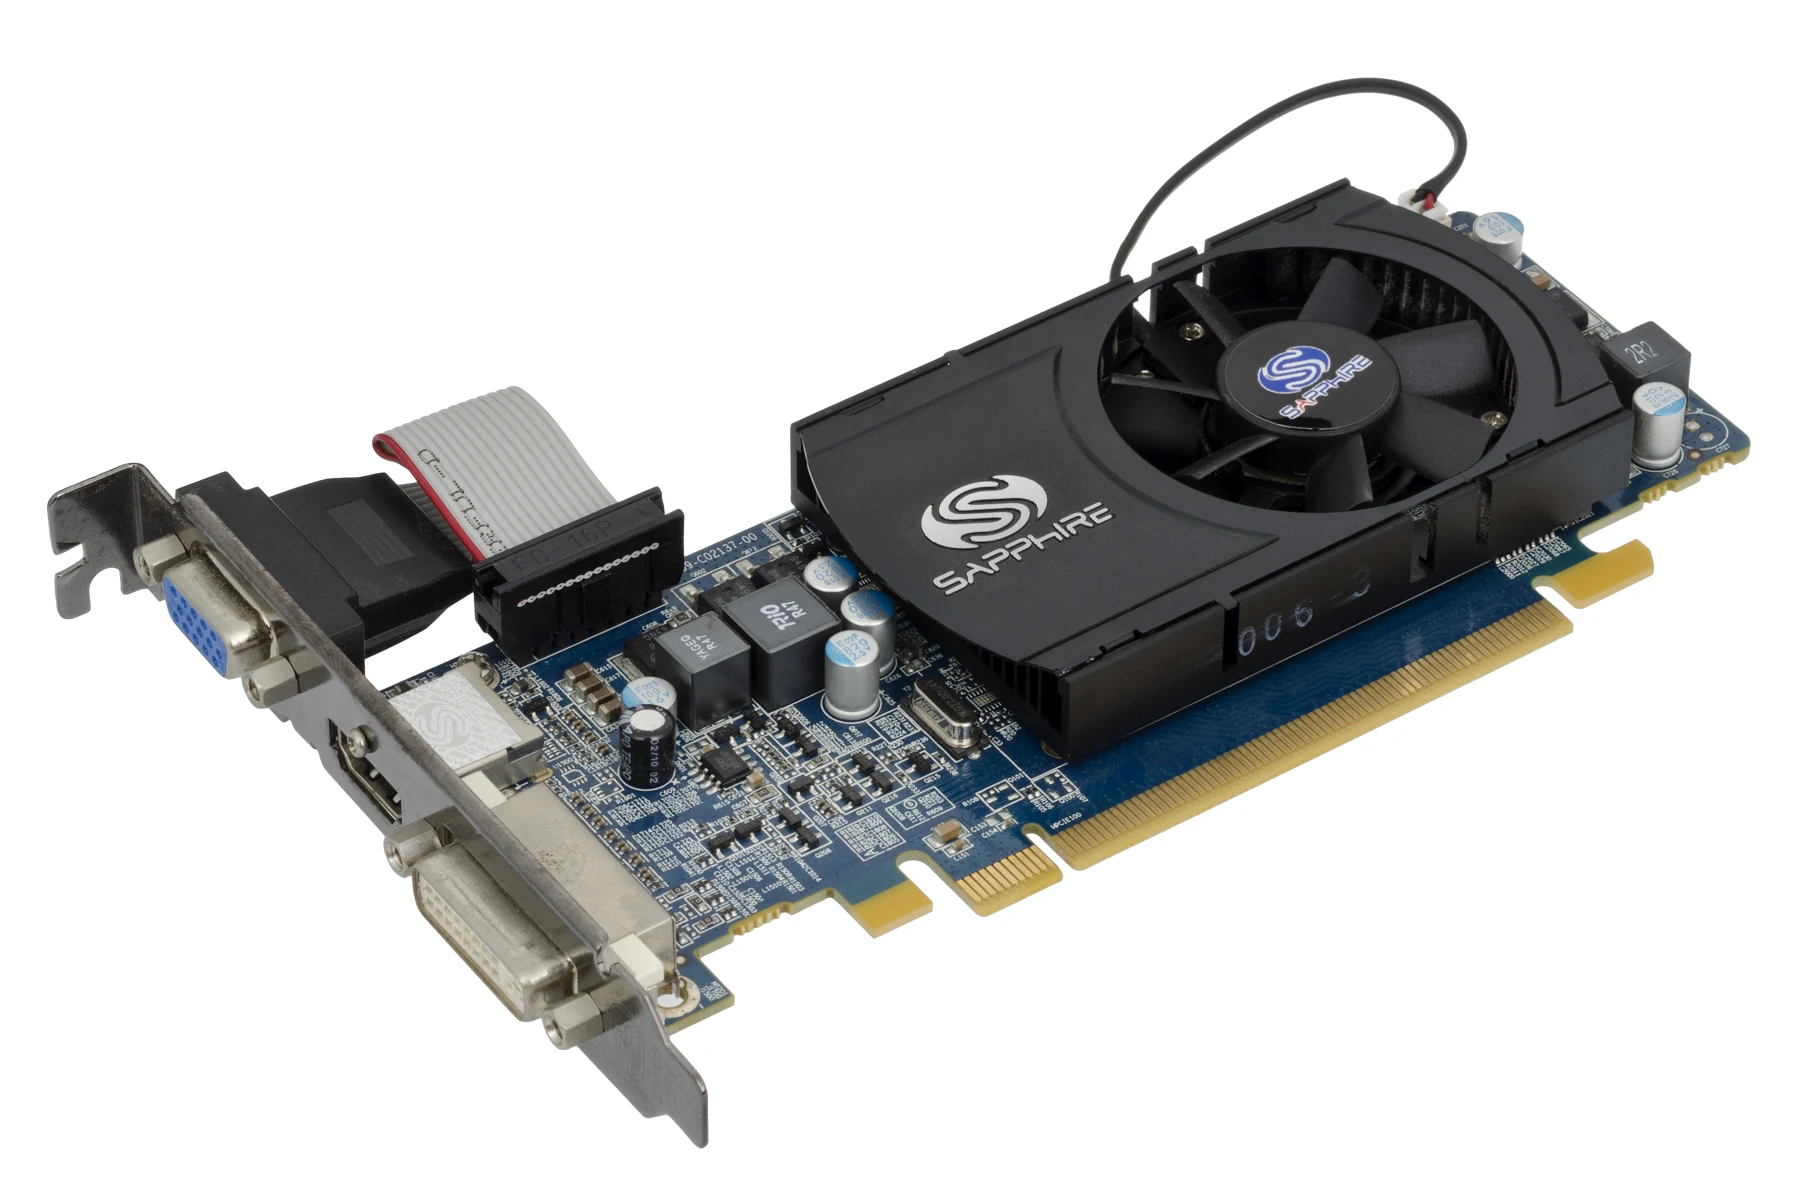
Why does an AI model run on one graphics processing unit, or GPU, but fail on another—even when both devices can perform AI calculations? The model needs enough working memory and a supported way to execute its operations. Its stored weights are only part of that requirement, and software support can differ between GPU architectures. [1] [4]
The useful comparison is the exact model, workload and software configuration, not simply which GPU is newer. A model can fail while loading, run out of memory during a longer request, or encounter an unsupported operation. It can also run correctly yet respond too slowly for the intended application. These are different problems, with different explanations.
Show less
On this page 11 sections
- Key Takeaways
- First, separate loading, running and running well
- The memory budget includes the work, not just the model file
- Memory capacity and memory bandwidth answer different questions
- The numerical format needs a compatible software kernel
- Running a model is not the same job as training it
- Compatibility belongs to a versioned software stack
- What the failure tells you—and what it does not
- Important Points / Key Information
- Examples / Supporting Information
- Conclusion
Part of our computer hardware technology guide library
Key Takeaways
- Loading the weights does not prove that the whole request fits in GPU memory.
- Memory capacity determines available space; bandwidth concerns data transfer, not an installation guarantee.
- The exact numerical representation needs a kernel supported by the GPU and installed software.
- Training needs update-related state that inference does not, and compatibility can change with software versions.
First, separate loading, running and running well
A model’s weights are the numerical values learned during training. Loading them makes those values available to the program; it does not prove that every operation needed for a request can execute, or that enough memory remains for the request itself. [1] [4]
A successful short response establishes less than sustained operation under heavier use. Longer inputs, longer generated outputs and more requests in progress can change the working-memory demand. The application also needs an acceptable response time and useful output, not merely an absence of error messages. [2]
That is why a compatibility statement needs context: which model version and representation, which GPU, which software release, and what kind of work? Without those details, “this model works on a GPU” is incomplete.
The memory budget includes the work, not just the model file
GPU memory must accommodate the values used at the busiest point of execution. Alongside weights, the program needs intermediate results, called activations, and temporary space for operations. Runtime allocations and kernel workspaces—the scratch space used by GPU routines—count too. A brief allocation peak can exhaust memory even if the weight file looked small enough. Hugging Face’s memory guide explicitly describes such temporary peaks. [1]
For a language model generating text, a key-value cache, or KV cache, often retains attention-related results from tokens already processed. Tokens are the pieces of text handled by the model. Reusing these results avoids repeating earlier work, but the cache itself occupies memory. A longer conversation can therefore need more memory without changing the model’s weights. [2]
Cache growth depends on the implementation and attention design. Some layers use a sliding window or chunks that limit the retained state, while other caches reserve space ahead of time. There is no single memory requirement that can be inferred from a model’s parameter count alone. [2]
Requests running together also need working state. Batch size describes how many inputs are processed together; concurrency describes how many requests are active. Their exact memory effect depends on scheduling and sharing. Available memory matters too: allocations already in use are not free space for the new workload.
Moving supported cache state to the computer’s main memory can reduce GPU-memory pressure. It changes where the data lives rather than removing it, and transfers can reduce generation throughput. More host memory is not a free extension of GPU memory with identical performance. [2]
Memory capacity and memory bandwidth answer different questions
Capacity is the amount of data the memory can hold. Bandwidth is the rate at which data can be transferred. Insufficient available capacity can stop a workload; limited bandwidth can make a workload wait for data even when it fits. Faster arithmetic cannot by itself create missing memory space.
NVIDIA’s A100 specifications illustrate why those measures should stay separate. The A100 80GB PCIe and SXM variants both list 80GB of HBM2e, a type of high-bandwidth GPU memory. Their listed memory bandwidth differs: 1,935 GB/s for PCIe and 2,039 GB/s for SXM. These are two distinct hardware variants with the same listed capacity. [3]
Those bandwidth specifications are not measured model-response speeds. The application’s arithmetic, data movement and chosen implementation determine what limits it. Equal memory capacity therefore does not establish equal performance, and a higher bandwidth figure does not establish that an otherwise incompatible model will run.
The numerical format needs a compatible software kernel
Precision describes how numerical values are represented. Quantization uses lower-precision representations for selected model values to reduce their storage. But a smaller representation still needs software that understands it and an execution path supported by the hardware. vLLM’s documentation lists support by quantization implementation, not just by the number of bits. [4]
A kernel is a software routine that carries out an operation on the GPU. A model may need particular matrix-operation or attention kernels. The GPU architecture’s capabilities and the kernel’s requirements must match; enough memory does not substitute for a missing implementation. [4]
One bounded example comes from vLLM, an inference and serving engine. In its quantization table checked on 6 November 2026, NVIDIA’s Ampere architecture is marked supported for AWQ and GPTQ, two quantization implementations, and for llm-compressor INT8 W8A8. It is marked unsupported for llm-compressor FP8 W8A8. [4]
W8A8 denotes eight-bit weights and eight-bit activations in those named schemes. INT8 is an integer representation; FP8 is a floating-point representation. Equal bit counts do not make the schemes interchangeable. The table concerns those vLLM implementations: it does not say that all FP8-related execution paths, or all AI programs, have the same restriction. [4]
This also separates compatibility from speed. A supported path is a prerequisite for using that implementation, not a certificate of useful latency or unchanged model quality. The exact representation and workload still need evaluation; the support chart explicitly says it can change. [4]
Running a model is not the same job as training it
Inference applies an already trained model to an input. Training updates its weights. That update process needs additional state: gradients describe how weights should change, and an optimizer uses those gradients, often retaining its own information across steps. Training also saves intermediate activations needed to calculate the updates. [1]
These allocations explain why a GPU can run inference for a model yet lack memory for a particular training setup. Batch size and sequence length can increase saved-activation memory, so changing the training workload can alter whether it fits even when the model architecture stays the same. [1]
There is no universal training-memory multiplier. The optimizer, numerical representations and training method change the budget. Nor is inference automatically easy: a large model serving long contexts may still need substantial memory. Compare the actual jobs, not an assumption that every GPU able to answer a prompt can also train the model. [1] [2]
Compatibility belongs to a versioned software stack
The software stack is the set of components between the application and the device: the framework or serving engine, its libraries and kernels, the driver, and the tools used to build them. A GPU generation name alone does not identify that combination. The installed release must support the model and the required execution path. [4] [5]
NVIDIA’s CUDA support guidance dated 4 August 2025 provides a useful distinction. It states that CUDA 13.0 removes offline compilation targets below compute capability 7.5, covering Maxwell, Pascal and Volta GPUs. Compute capability identifies an NVIDIA GPU architecture’s features; offline compilation means building GPU code for the target device ahead of execution. [5]
Removing a target from a new compiler does not physically disable the GPU. NVIDIA explains that applications built with older toolkits can continue to run on hardware supported by the driver. But that is not a blanket promise that a current framework, kernel or maintained deployment will support the same device. Building new software and running an existing compatible binary are separate questions. [5]
The dated example is not an A100 support cutoff or a universal GPU lifespan. It shows why “it worked before” and “the newest software can build and run it” can both be truthful observations about different configurations.
What the failure tells you—and what it does not
An out-of-memory error points to an allocation that could not be satisfied. It does not automatically mean the weights alone exceed the device’s capacity. If loading succeeds but a longer request fails, cache growth or temporary working space is a relevant possibility, not a diagnosis established by this article. [1] [2]
An unsupported-operation or kernel error raises a different question: does this model representation have an execution path for the installed software and GPU? Increasing available memory would not create that missing support. The precise error and the matching version’s documentation matter. [4]
A workload that completes slowly has passed more checks than one that cannot start, but still may not meet the application’s needs. Response time and throughput—the amount of work completed over time—are different measures. Neither a successful load nor a GPU specification establishes them for a real service.
Can the same GPU stop working after a software update?
The same hardware can become incompatible with a changed software path. A new build may target different architectures or use a kernel unavailable for the old configuration. That does not establish physical failure. Conversely, retaining an old working build does not by itself establish ongoing maintenance or security support. Compatibility needs the versions, not only the device name. [4] [5]
Important Points / Key Information
A meaningful compatibility claim specifies the model and its numerical representation, the complete workload, available GPU memory and the software versions. “Fits,” “has a supported execution path” and “meets the application’s performance needs” are separate conclusions.
The quickest way to understand the difference between two configurations is to identify which condition changed. Memory pressure calls for a full working-set explanation; an unsupported kernel calls for implementation-level evidence. Neither condition can be settled by a newer-generation label alone. [1] [4]
Examples / Supporting Information
Consider a fictional document assistant using the same model on two GPUs. On the first, its supported representation loads and short requests complete. On the second, the weights also load, but a longer document causes the total working state to exceed available memory. This illustrates a workload-capacity limit, not proof that the second GPU cannot run any request from that model.
Now change the software path rather than the document length. Suppose the assistant uses the llm-compressor FP8 W8A8 implementation on Ampere under the vLLM support table discussed above. That named path is marked unsupported. Extra free memory would not alter the table’s compatibility restriction. A different representation would be a different configuration requiring its own checks. [4]
The first scenario is hypothetical, not a measured failure trace; the second applies a specific documented support entry. Together they show why a memory error and an implementation restriction should not be described as the same problem.
Conclusion
An AI model can work on one GPU but not another because its full working state does not fit, its required numerical implementation is unsupported, or the software versions target different capabilities. Training introduces another budget, while bandwidth and execution efficiency influence how well a compatible workload runs.
The model name and GPU name are only the beginning of the explanation. The complete configuration tells you whether it can load, carry out the intended work and deliver acceptable results. That is more useful than treating one failure as a verdict on the GPU’s age or on every possible use of the model.
How we checked thisSources (5)
We keep source links private so your reading stays on techduopulse. Each note names the publisher and document we checked.
Hugging Face — Transformers: GPU memory usage; date not stated; accessed 6 November 2026
Primary source · Memory budget; training versus inferenceHugging Face — Transformers: Cache strategies; date not stated; accessed 6 November 2026
Primary source · Inference working memory and offloadingNVIDIA — A100 Tensor Core GPU: memory specifications; date not stated; accessed 6 November 2026
Primary source · Capacity versus bandwidthvLLM — Quantization: supported hardware; displayed page date 14 September 2026; accessed 6 November 2026 — 14 September 2026 (displayed page date)
Primary source · Numerical formats and kernels; documented exampleNVIDIA — Navigating GPU Architecture Support: A Guide for NVIDIA CUDA Developers; 4 August 2025; accessed 6 November 2026
Primary source · Versioned compatibility; compilation versus existing binariesInitial source-backed owner-authorized manual publication. Original reviewed article facts, metadata and licensed real photograph preserved. Schema-only body and citation projections are recorded privately; no hands-on test or qualified human certification claimed.